 AA-Robotics
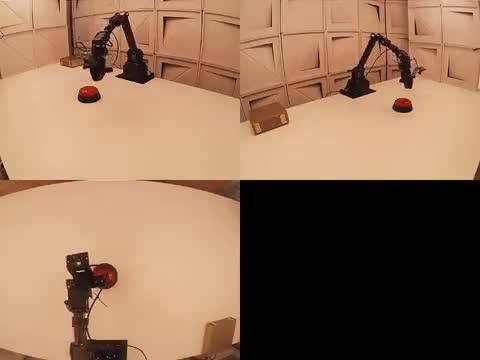
Artificial AnalysisMaintainer ↗8 tasks, press a button, place a toy, pour a drink, tidy blocks, match shapes, write hello world, build a tower and measure a box.
As of November 17, 2026, GPT-6.2 Astra leads with 79.0, followed by GPT-6.2 Sol (78.0) and Claude Fable 5.2 (75.0). Official leaderboard ↗
Leaderboard
- Tasks
- 8
- Attempts / task
- 1
- Median cost / task
- $7.61
- Median time / task
- 31 min 12 s
Overall vs speed
Published time per task attempt
Overall vs cost
Published cost per task attempt
Task score 0 to 100, one attempt per task, judged by a person. Overall scores for GPT-6.2 Astra, GPT-6.2 Sol, Claude Fable 5.2, Gemini 4 Hydrogen and Gemini 4 Carbon come from a chart in Artificial Analysis's November 17 GPT-6.2 article, which gives no harness, effort setting or task scores. They are held, not counted in the index, until Artificial Analysis publishes the runs.
 GPT-6 Astra69.4100100100$16.3630 min 18 s5GPT-6.1 Sol64.61001000.00$1.9328 min 06 s
 Gemini 4 Argon55.3100100100$7.6152 min 24 s8
 Claude Opus 5.548.810010025.0$6.7531 min 42 s9Claude Fable 5.146.310010030.0$9.7331 min 12 s
Tasks
8 tasks. Hover a task to play its clip (8 of 8).
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
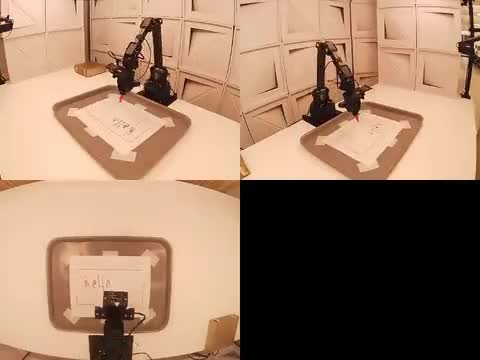 ▶ Clip
 ▶ Clip
 ▶ Clip
Methodology
- Scoring
- Pass/fail + partial
- Time cap / attempt
- —
- Control rate
- —
- Models in index
- 5 of 10
Scoring. A human judge awards 100 for the pass criterion, 0–99 for partial progress.
Who runs it. Independent evaluator (Artificial Analysis), one human-judged attempt per task.
Robots. Hiwonder NexArm (one arm).
Note. Coding agents only. Research preview.
Time per attempt. Published or measured for 5 of 5 models.
Cost per attempt. Published for 5 of 5 models.