 Poke & Wiggle
 GmbHMaintainer ↗10 tasks in basic skills, high precision, two-arm handling and tool use, from sorting screws to plugging a DC jack and opening a toolbox with a screwdriver. Each on training, unseen in-between and unseen outside placements.
As of November 17, 2026, Claude Fable 5.2 leads with 65.0, followed by Gemini 4 Carbon (45.0) and Claude Opus 5.5 (39.0). Official leaderboard ↗
Leaderboard
- Tasks
- 10
- Attempts / task
- —
- Median cost / task
- $0.144
- Median time / task
- 88 s
Overall vs speed
Published time per task attempt
Cost isn’t published
Poke & Wiggle doesn’t report cost per attempt for enough models to chart. The table shows Playground’s estimates, marked est.; Methodology explains how they’re made.
Success rate (%). Robot models: 5,400 episodes each, fine-tuned by Poke & Wiggle on 10, 100 and 300 demonstrations per task, pooled. Coding agents (Claude Fable 5.2, Claude Opus 5.5, Gemini 4 Argon, GPT-6 Astra): 900 episodes each, writing robot code from 10 demonstrations with simulated and real practice. The index never compares the two groups.
 Claude Fable 5.265.073.069.052.0$2.58est.2 min 06 s2
 Gemini 4 Carbon45.047.049.038.0$0.733est.2 min 07 s3Claude Opus 5.539.044.048.026.0$0.556est.2 min 15 s4Gemini 4 Argon35.041.040.023.0$0.522est.1 min 42 s5
 GPT-6 Astra34.035.041.025.0$1.26est.2 min 12 s6
 Rho24.035.029.07.0$0.039est.43 s7
 MolmoAct221.031.025.07.0$0.039est.42 s8
 π0.516.023.019.05.0$0.034est.37 s9PWDiT-Flow14.021.016.04.0$0.043est.47 s10
 GR00T N1.710.013.012.04.0$0.041est.45 s11
 Mistral Large 47.08.011.02.0$0.144est.88 s
Tasks
10 tasks. Hover a task to play its clip (5 of 10).
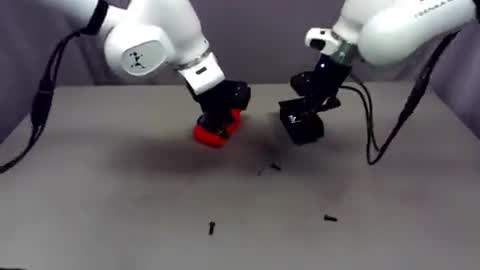 ▶ Clip
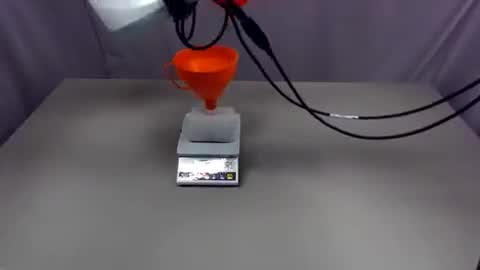 ▶ Clip
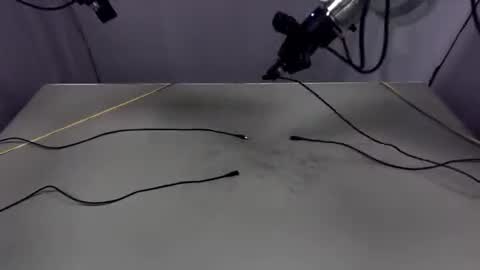 ▶ Clip
 ▶ Clip
 ▶ Clip
Methodology
- Scoring
- Human rating
- Time cap / attempt
- 1 min 43 s
- Control rate
- 30 Hz
- Models in index
- 11 of 11
Scoring. People rate every episode Excellent, Ok or Failed, overall and per step; Ok or Excellent counts as success.
Who runs it. Poke & Wiggle runs every episode, rated by people, and publishes its video.
Robots. Franka FR3 Duo (two-arm).
Note. Two tables. Robot models fine-tuned by Poke & Wiggle on 10, 100 and 300 demonstrations per task, and coding agents that write robot code in Poke & Wiggle's harness from 10 demonstrations. The two are not compared with each other.
Time per attempt. Published or measured for 11 of 11 models.
Cost per attempt. Not published. Estimated otherwise: Poke & Wiggle's published model-token cost to write and practise one task's policy ($232, https://pokeandwiggle.com/blog/agentic-robotics) spread over the 90 rated trials per task; trials then call the model only at decision points the code chose.; Poke & Wiggle's published model-token cost to write and practise one task's policy ($113, https://pokeandwiggle.com/blog/agentic-robotics) spread over the 90 rated trials per task; trials then call the model only at decision points the code chose.; Poke & Wiggle's published model-token cost to write and practise one task's policy ($47, https://pokeandwiggle.com/blog/agentic-robotics) spread over the 90 rated trials per task; trials then call the model only at decision points the code chose.; Poke & Wiggle's published model-token cost to write and practise one task's policy ($50, https://pokeandwiggle.com/blog/agentic-robotics) spread over the 90 rated trials per task; trials then call the model only at decision points the code chose..