 RoboChallenge
Maintainer ↗30 household tabletop tasks, grouped here by robot. Progress score and success rate.
As of November 17, 2026, Era0 (per-task) leads with 76.3, followed by DM0 (per-task) (72.3) and GigaBrain-0.1 (per-task) (68.3). Official leaderboard ↗ · Paper ↗
Leaderboard
- Tasks
- 60
- Attempts / task
- 10
- Median cost / task
- $0.232
- Median time / task
- 4 min 14 s
Progress vs speed
Published time per task attempt
Cost isn’t published
RoboChallenge doesn’t report cost per attempt for enough models to chart. The table shows Playground’s estimates, marked est.; Methodology explains how they’re made.
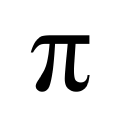
Entries are shown as name | entrant. Progress score 0 to 100 over 10 attempts per task. Entries trained as a separate checkpoint for each task are ranked as their own models, marked per-task. The multi-task entries pi05_generalist, pi0_generalist and DM0_generalist stand for π0.5, π0 and DM0.
 Era0 (per-task)76.364.385.975.8$0.181est.3 min 18 s2
 DM0 (per-task)72.362.058.578.6$0.227est.4 min 08 s3
 GigaBrain-0.1 (per-task)68.351.767.070.7$0.197est.3 min 35 s4
 Spirit v1.5 (per-task)67.251.061.169.5$0.258est.4 min 42 s5
 π0.5 (per-task)61.842.762.461.9$0.255est.4 min 39 s
 wall-oss-v0.1 (per-task)55.335.347.055.1$0.315est.5 min 45 sDM049.137.330.761.1$0.232est.4 min 14 s10π0 (per-task)46.428.347.147.7$0.267est.4 min 52 s
 X-VLA (per-task)34.821.342.540.7$0.201est.3 min 40 sπ0.531.317.733.827.6$0.257est.4 min 41 s
 RDT (per-task)28.815.021.645.9$0.239est.4 min 22 s
 CogACT (per-task)21.811.712.417.7$0.202est.3 min 41 s20π020.29.016.413.2$0.253est.4 min 37 s
 OpenVLA-OFT (per-task)8.75.06.415.5$0.215est.3 min 55 s
Tasks
60 tasks. Hover a task to play its clip (60 of 60).
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
Graded examples
Scoop with a small spoon · Qwen-RobotManip, 10 rollouts

| Rollout | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 | 9 | 10 |
|---|---|---|---|---|---|---|---|---|---|---|
| Points / 10 | 2 | 10 | 8 | 10 | 5 | 2 | 10 | 2 | 2 | 10 |
Rubric: hold bowl 2 · scoop 3 · pour 3 · return spoon 2.
Run score 61 / 100; 4 of 10 rollouts complete. Three stopped after holding the bowl, one after scooping, one after pouring.
Methodology
- Scoring
- Staged rubric
- Time cap / attempt
- —
- Control rate
- —
- Models in index
- 14 of 22
Scoring. On-site tester awards stage points out of 10; 0.5 off per retry.
Who runs it. Operator runs the robots, entrant runs the model remotely.
Robots. UR5, Franka, ARX5, ALOHA.
Note. We use the final v1 board (22 entries that completed all 30 tasks).
Time per attempt. Published or measured for 14 of 14 models.
Cost per attempt. Not published. Estimated otherwise: one H100 at $3.29 per hour (Lambda on-demand, Oct 2026) × time. GPU price source ↗