 Embodied First Exam
 teamMaintainer ↗Standard, real-time and privileged modes. Coding agents only.
As of November 17, 2026, Claude Fable 5.2 leads with 49.6, followed by GPT-6 Astra (34.4) and GPT-6.1 Sol (32.2). Official leaderboard ↗ · Paper ↗
Leaderboard
- Tasks
- 498
- Attempts / task
- 1
- Median cost / task
- $5.29
- Median time / task
- 1 h 12 min
Standard vs speed
Published time per task attempt
Standard vs cost
Published cost per task attempt
Share of tests solved (%). Privileged mode gives the agent extra state information.
 Claude Fable 5.249.640.779.5$12.5959 min 02 s2
 GPT-6 Astra34.431.578.5$24.611 h 12 min3GPT-6.1 Sol32.220.471.9$2.15est.50 min 20 sest.4Claude Opus 5.525.07.459.6$5.5952 min 23 s5
 Gemini 4 Argon24.19.342.7$5.291 h 15 min6
 Kimi K3.1 Pro10.17.437.9$8.001 h 22 min7Gemini 3.8 Flash6.41.923.8$7.271 h 19 min8
 Qwen3.8 Max3.71.99.5$3.811 h 21 min9
 DeepSeek V4.1 Flash3.11.916.9$0.4161 h 08 min10
 GLM 5.3 Flash2.40.009.7$0.6161 h 28 min
Tasks
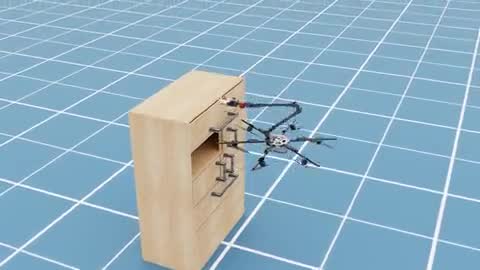
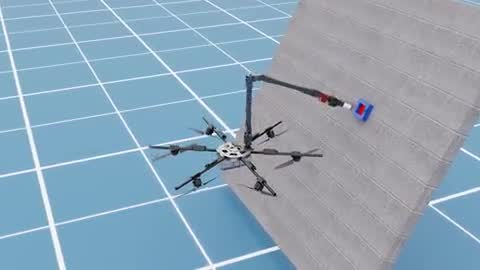
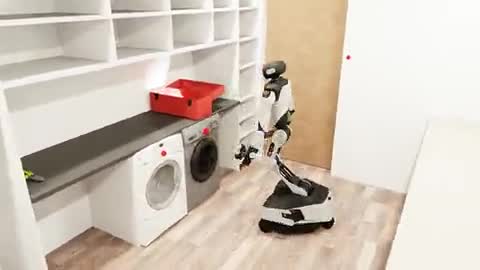
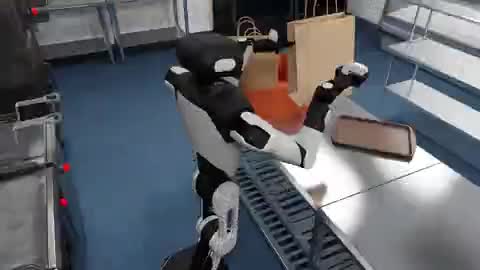
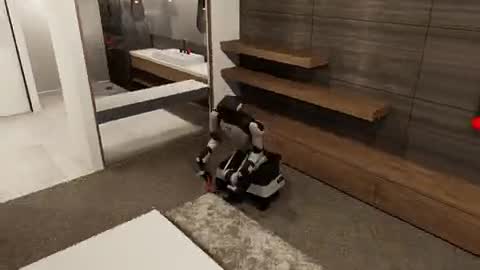
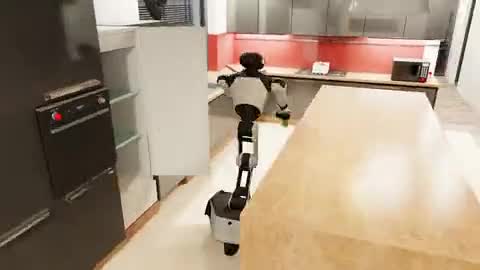
498 tasks. Hover a task to play its clip (498 of 498).
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
Graded examples
Turn off the sink faucet · standard mode
| Agent | Standard |
|---|---|
| Claude Opus 5.5 | Pass |
| Gemini 4 Argon | Pass |
| Kimi K3.1 Pro | Pass |
| DeepSeek V4.1 Flash | Pass |
| GPT-6 Astra | Fail |
| GLM 5.3 Flash | Fail |
| Qwen3.8 Max | Fail |
| Gemini 3.8 Flash | Fail |
Check: the faucet handle ends outside 0.40–π rad after the last step, and the task was not already solved at the start.
Methodology
- Scoring
- Code check
- Time cap / attempt
- 1 h 00 min
- Control rate
- —
- Models in index
- 10 of 10
Scoring. Simulator success function after the agent's last step, pass/fail.
Who runs it. Benchmark team runs every entry.
Robots. 44 simulated robots across 31 suites.
Note. Only coding agents are tested here.
Time per attempt. Published or measured for 9 of 10 models. Estimated otherwise: time cap 3600 s × (1 − success/2).
Cost per attempt. Published for 9 of 10 models. Estimated otherwise: GPT-6.1 Sol's median published cost per attempt on other boards.