 EFE-98
PlaygroundMaintainer ↗A 98-test short form of Embodied First Exam's standard mode, from its 18 cheapest runnable suites, frozen before any model was run. Coding agents only.
As of November 20, 2026, GPT-6.2 Astra leads with 76.5, followed by Claude Fable 5.2 (50.0) and GPT-6 Astra (38.5). Official leaderboard ↗
Leaderboard
- Tasks
- 98
- Attempts / task
- 1
- Median cost / task
- $2.86
- Median time / task
- 33 min 49 s
Share of tests passed (%), one attempt per test. GPT-6.2 Astra was run by Playground on all 98 tests. The other scores are computed from Embodied First Exam's published per-test results on the 96 tests that could be matched. Scores of models with a full exam score count only as opponents; since November 20 that includes GPT-6.2 Astra, and Qwen3.8 Max, which the exam no longer lists, counts here.
 GPT-6.2 Astra76.5$5.0923 min 54 s2
 Claude Fable 5.250.0$6.3525 min 27 s3GPT-6 Astra38.5$9.6327 min 13 s4GPT-6.1 Sol33.3$1.3530 min 30 s5
 Gemini 4 Argon28.1$2.8639 min 52 s6Claude Opus 5.527.1$2.4322 min 50 s7
 Kimi K3.1 Pro12.5$3.6637 min 56 s8Gemini 3.8 Flash9.4$3.7933 min 49 s9
 Qwen3.8 Max5.2$2.0646 min 43 s10
 DeepSeek V4.1 Flash4.2$0.29540 min 57 s11
 GLM 5.3 Flash2.1$0.37239 min 29 s
Run it yourself
EFE-98 runs on Embodied First Exam's own runner and pass or fail checks, unchanged. You need the exam at the version below and the list of 98 tests.
- Exam version
- ebd10b6
- Mode
- Standard, 1 attempt
- GPT-6.2 Astra cost
- $499
- GPT-6.2 Astra time
- 7 h 54 min
Set up the exam
Clone Embodied First Exam at the version we froze the test list against, then follow its README to install the runner and build the simulator images.
git clone https://github.com/mll-lab-nu/embodied-first-exam
cd embodied-first-exam
git checkout ebd10b62b0f4d5c299c3249555d2746e9eb51880
Get the test list
One test name per line, 98 in all, across 18 of the exam's suites.
Download tests.txt ↓curl -O https://withplayground.ai/leaderboard/efe-98/tests.txtRun each test once
Standard mode, one attempt per test, with the exam's default time budgets, tools and network rules. These are the settings of our GPT-6.2 Astra run; set AGENT, MODEL and EFFORT for the entry you are testing.
while read -r test; do
  AGENT=codex MODEL=openai/gpt-6.2-astra EFFORT=high MODES=standard \
  JOBS="$PWD/efe98-jobs" RESULTS="$PWD/efe98-results" \
    bash scripts/run_agent_batch.sh efe98 "$test"
done < tests.txt
Score it
The score is tests passed divided by 98. A test stopped before grading by an infrastructure failure, an API error or a usage limit is discarded and rerun once. A test that was graded keeps its result.
What the machine needs.
- A machine that runs Docker with NVIDIA GPUs. We use four RTX A6000 cards on Ubuntu 22.04.
- Four suites use Isaac Sim, which needs NVIDIA's graphics libraries (libnvidia-gl) at the same version as the installed driver.
- The runner's scripts need Python 3.11 or newer.
- To run tests side by side on several GPUs, apply our nine-line runner patch and set GPU_DEVICE for each lane. As shipped, every test asks Docker for the first GPU. gpu-pin.patch ↓
Get listed. To have a result listed here, send the run's jobs folder, which holds each test's result and agent log, to contact@withplayground.ai.
Tasks
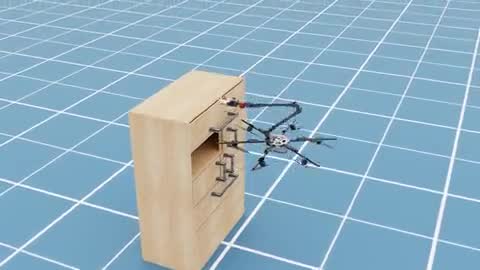
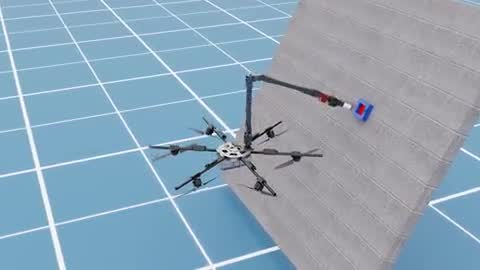
98 tasks. Hover a task to play its clip (98 of 98).
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
 ▶ Clip
Methodology
- Scoring
- Code check
- Time cap / attempt
- 1 h 00 min
- Control rate
- —
- Models in index
- 2 of 11
Scoring. Embodied First Exam's own simulator success function after the agent's last step, pass/fail.
Who runs it. Playground runs each new entry with the exam's own runner and verifier.
Robots. Simulated robots across 18 of Embodied First Exam's suites.
Note. Counts only for models with no full Embodied First Exam score. The exam's ten published agents are listed, from their published per-test results, as opponents only.
Time per attempt. Published or measured for 2 of 2 models.
Cost per attempt. Published for 2 of 2 models.
Cost and time for the other entries. The exam's ten published agents have no result of their own here. Their cost and time per test are the exam's published per-suite averages (its own cost estimate and agent time, over every graded trial in all modes), weighted by EFE-98's tests per suite, so they describe this test mix rather than a run of it. GPT-6.2 Astra's cost is its logged tokens at API list price, a different method from the exam's estimate.